- Subject
- Microsoft 365 & SharePoint
- Filed
- Source
- Lucas Magnum
- Loans
- 452
Veeam DiskLib Error 13: How Job Scheduling and Storage Snapshots Were Investigated
Three parallel datastore chains reduced overlap across shared LUNs. Over three weeks, the NFC error and retained snapshots did not recur, while physical headroom improved.
An intermittent Veeam DiskLib error 13 can be the visible symptom of a wider backup workflow problem. In this VMware environment, jobs sometimes failed while trying to create an NFC download stream, while other sessions succeeded. The investigation also found overlapping schedules, retained storage snapshots, and physical capacity close to its limit.
The environment had 27 hourly VMware backup jobs protecting more than 300 VMs. It ran Veeam Backup & Replication 13.0.1.1071, VMware vCenter 8.0.3, and an IBM FlashSystem FS5200. The eventual response coordinated job schedules with datastore and LUN boundaries, keeping three groups active in parallel while sequencing jobs within each group.
What the failures showed
The reported error appeared while Veeam prepared a VM for processing:
Failed to prepare VM for processing: DiskLib error: [13].The file is locked or in use -- File open failed: File not open
Failed to create NFC download stream.
NFC path: [nfc://conn:[VCENTER],nfchost:[HOST-ID],stg:[DATASTORE-ID]@[VM]/[VM].vmx].
Agent failed to process method {Transfer.FileToText}.
The same message appeared inconsistently. Some runs completed; others failed. One session reached 100% progress with three VM tasks successful and two failed. That result is a reminder to check each task outcome: the session progress indicator alone did not mean every VM had been backed up.
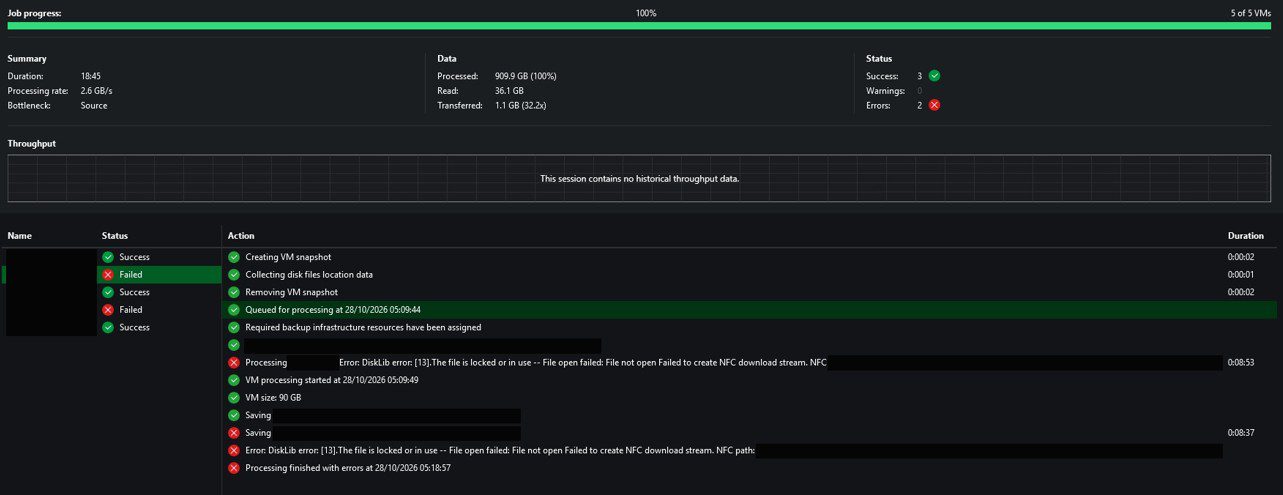
Figure 1 – Three VM tasks succeeded and two failed. The status indicators and error remain visible.
Task limits were already configured, but jobs with independent schedules could still overlap. Some sessions were processing data while others waited for resources or completed other work. A queue can be an expected result of a task limit; by itself, it does not establish that the environment is overloaded. The more significant pattern was the combination of overlapping execution, intermittent errors, storage snapshots remaining after backup activity, and low physical headroom.
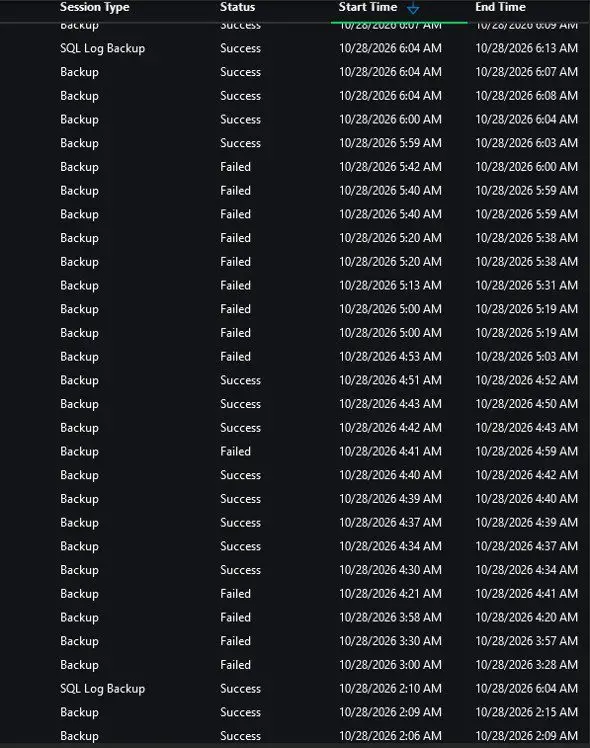
Figure 2 – Session history showing overlapping runs and mixed outcomes.
What DiskLib error 13 does and doesn’t establish
NFC means Network File Copy in this VMware context. The error identified a failed attempt to access a VM configuration file, with the message reporting that the file was locked or in use. In the illustrated session, saving the .vmx file completed, while access to the .nvram file failed.
Veeam KB1198 documents this error family and lists DNS, connectivity, permissions, and file locks among the paths to investigate. The full error and surrounding session details are more useful than interpreting the number 13 alone.
The message did not establish virtual disk corruption or identify the lock owner. Nor does an NFC error involving a configuration file prove that VMDK data was read using NBD or that a transport fallback took place. Confirming a lock-related cause would require evidence such as the VM’s host at failure time, migration timestamps, the host serving the NFC request, and information identifying the lock owner.
DRS activity and the snapshot lifecycle
DRS activity around backup execution drew attention during the investigation. Here, DRS means VM placement and compute resource balancing across ESXi hosts, with vMotion used for host migrations. It is distinct from Storage DRS and Storage vMotion, which relate to storage placement and migration. The observed movements were a lead to examine, not proof that a migration caused a particular file lock. Normal vMotion activity alone does not show that something is wrong.
The storage workflow also involved two snapshot lifecycles. In simplified form, a Backup from Storage Snapshots job can create VMware snapshots for the VMs being processed, capture a storage snapshot of the relevant volume or LUN, remove the VMware snapshots, read VM data from the storage snapshot, then remove the temporary storage snapshot after processing.
That sequence means a VMware snapshot can be gone while the storage snapshot remains in use. In the example session, successful VMware snapshot removal did not demonstrate that storage cleanup had finished.
Understanding the IBM storage dependency
Retained snapshots prompted an initial parent-and-child analogy, but individual VMs are not the right objects for describing storage dependencies. If FlashCopy is in use, the relevant relationships involve source and target volumes and their mappings. A dependency can require data to be preserved or copied before a relationship is stopped or removed safely. Seeing multiple snapshots for one volume does not, on its own, prove a cleanup defect or reveal the dependency chain.
There is another configuration detail to establish before drawing conclusions. Veeam KB4650 explains that supported IBM configurations can use storage volume snapshot functionality instead of FlashCopy, including automatic selection on systems that support it. The mechanism depends on firmware, system capabilities, and plug-in implementation. The FS5200 model name alone does not identify which method a backup job used.
The working hypothesis was that overlapping jobs against shared volumes contributed to longer-lived snapshots and more difficult cleanup. Establishing a specific storage dependency would require the IBM firmware and plug-in versions, the storage object relationships, and cleanup logs. Those details were not available in this case.
Keep three concurrency controls separate
Three controls affect backup concurrency, and they solve different scheduling questions:
- Proxy and repository task limits regulate how much work those components handle.
- Job schedules determine when separate workflows start.
- The number of VMs per storage snapshot determines how VMs are divided into snapshot batches.
Veeam’s current documentation describes storage snapshot batches being processed in parallel. Smaller batches can shorten the time VMware snapshots remain open, but can create additional storage snapshots. That setting does not guarantee one active snapshot per LUN. The historical value configured in this environment was not recorded.
The practical goal was to coordinate operations against shared storage while retaining useful concurrency. That required looking at the combined schedule, including preparation, retries, processing, and cleanup—not just the start time of an individual job.
Three parallel chains, sequenced within each datastore group
Before reorganizing jobs, the administrator and backup operator reviewed protection requirements: which servers needed frequent protection and how the schedule could meet those needs. They then organized the work into three groups, each corresponding to a datastore and its underlying LUN.
The three groups ran in parallel. Within each group, a job started after its predecessor completed. This retained parallel execution across the three datastore groups while reducing overlapping jobs against the same LUN. It did not serialize the entire backup environment, and the schedule did not impose a storage-level lock.
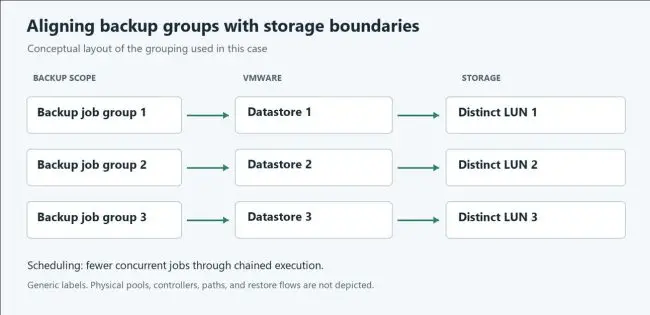
Figure 3 – Each datastore group used a sequential job chain, with all three chains running in parallel. The diagram is conceptual and does not show the full physical topology.
Job chaining has trade-offs. A long run or retries can delay later jobs, affect full-backup timing, and leave other resources underused. Veeam documents job scheduling and task limits as tools for managing infrastructure load; chaining is one possible arrangement, not a universal instruction to serialize backups.
The groups also needed to reflect where VM files and disks actually lived. A disk on another LUN can preserve overlap between groups. And separate LUNs may still share a storage pool, controllers, cache, disks, or paths. Matching jobs to LUN boundaries can coordinate snapshot activity, but it does not make the underlying hardware independent.
Manual cleanup and capacity change
Existing storage objects that had accumulated required separate attention. The infrastructure administrator performed a manual cleanup through the storage CLI, identifying objects by the naming convention used by the Veeam integration. The command history and a complete inventory of removed object types were not available, so the cleanup procedure cannot be reconstructed from the record.
A naming prefix alone does not show that an object is unused or safe to remove. Any repeat of this work would need to establish the actual object type, its dependencies, and the supported removal procedure. The cleanup was distinct from the job scheduling and datastore grouping changes.
Capacity was already a pressing concern. An earlier storage view showed 19.68 TiB physically used out of 19.94 TiB, with 267.90 GiB available—about 98.7% physical utilization. A later view showed 9.26 TiB used and 10.68 TiB available, with the same displayed total capacity.
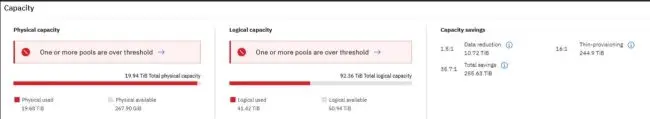
Figure 4 – Earlier capacity view, with physical usage close to the displayed total.

Figure 5 – Later capacity view, with more physical headroom and the displayed total unchanged.
The displayed used capacity fell by about 10.42 TiB, or 52.9% of the earlier used amount. This is a comparison of capacity readings, not a measured performance gain, and it does not establish that snapshots accounted for every unit of released space. The interface shows rounded TiB totals and used values, while the earlier available figure is displayed in GiB; subtracting the displayed rounded values may not reproduce the separately reported available capacity.
What the follow-up supports
For approximately three weeks after the combined changes, neither the NFC error nor the retained-snapshot accumulation recurred. The three datastore chains remained parallel, with jobs sequenced inside each chain. The later capacity view also showed substantially more physical headroom.
This is an observation after both schedule changes and a manual cleanup. It does not isolate the effect of either action. The available records also lack a counted series of sessions for calculating a before-and-after failure rate, the lock owner, the exact storage dependency mechanism, and IBM firmware and plug-in versions.
No restore test or measured RPO or RTO was recorded. The evidence supports a narrower conclusion: the two reported symptoms did not recur during roughly three weeks of observation, and displayed physical usage dropped substantially.
For administrators facing a similar pattern, the useful checks are the failed file operation and its host context; the combined schedule, including retries and cleanup; the age and removal status of VMware and storage snapshots; and the placement of VM files and disks across datastores and LUNs. Then record the observation period and capacity readings. Those details make it easier to tell whether a change stabilized the workflow and whether backup completion still meets protection requirements.


